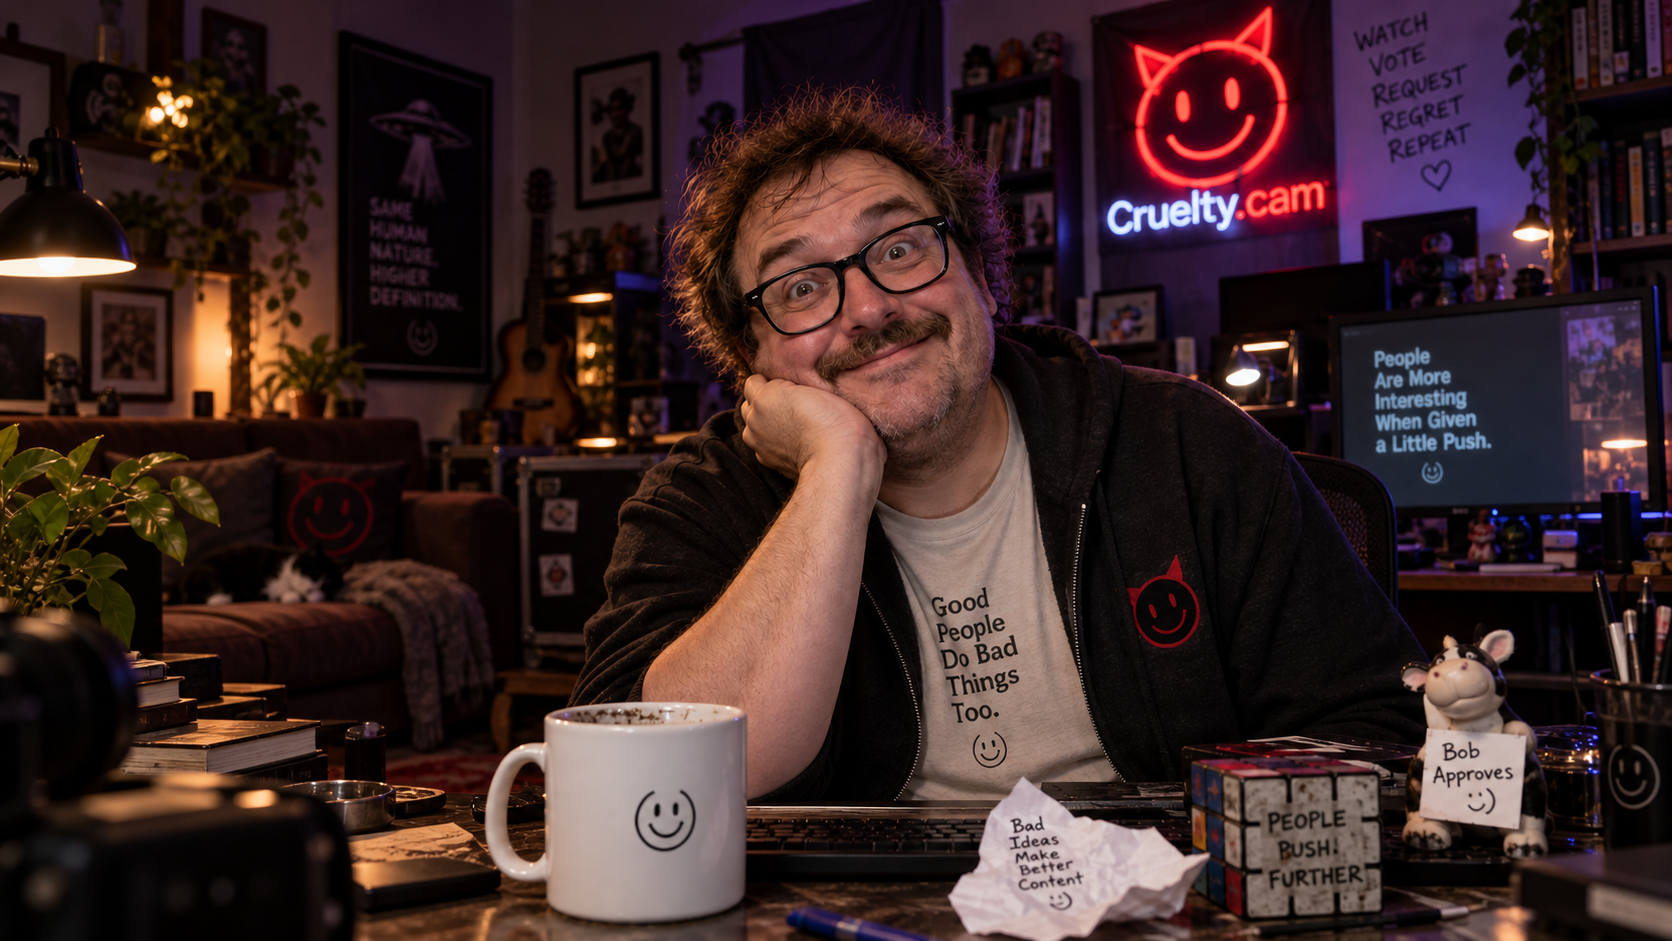
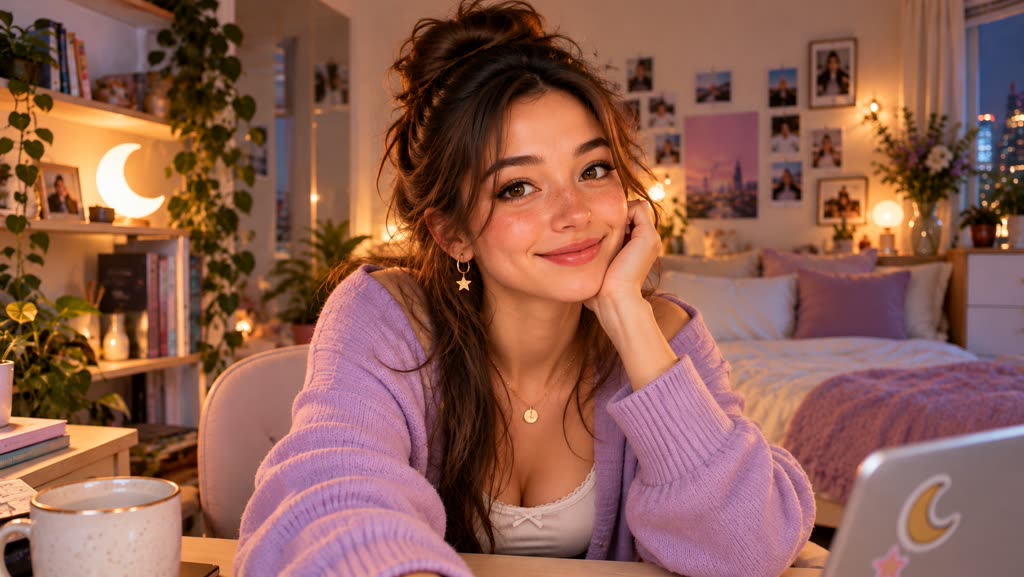
Same characters, different inputs
Audio-driven models use Bob and Luna's five-second recordings. Reactor's text-driven models synthesize a new voice; their results are labeled and are not an exact audio comparison. Portrait models receive each character's production portrait.